Prompt contains gender bias guardrail
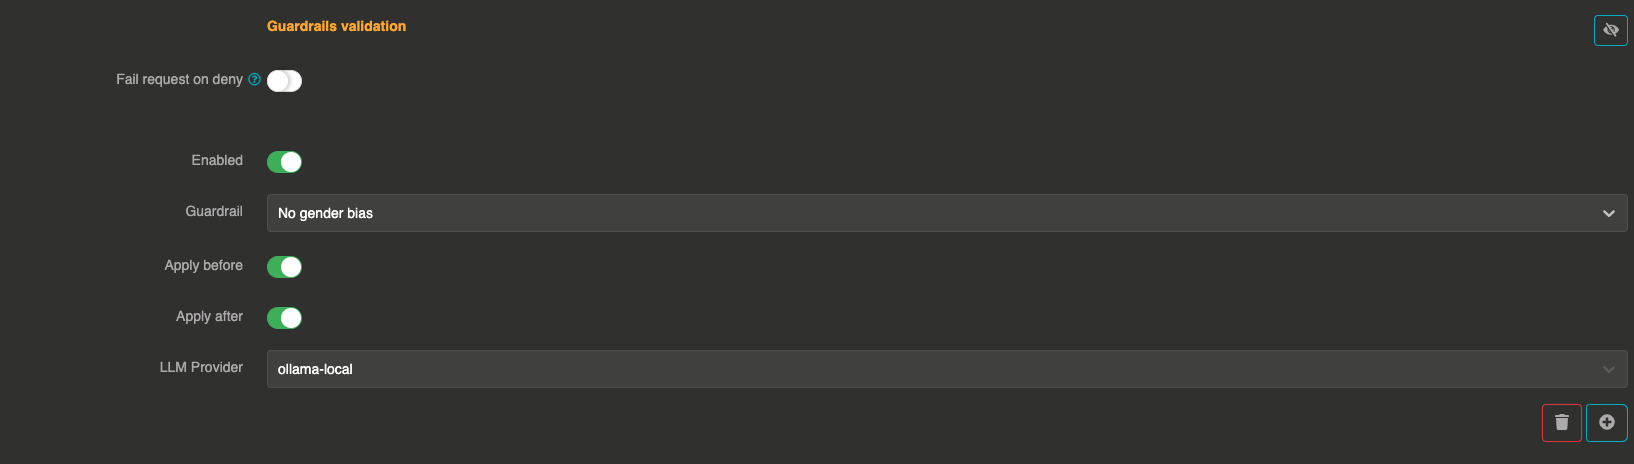
A mechanism that identifies and reduces biased language related to gender in user prompts, promoting fairness and inclusivity in AI-generated content. It uses a dedicated LLM provider with a hardcoded prompt to detect gender bias.
It can be applied before the LLM receives the request (blocking biased prompts) and after to filter biased responses.
How it works
The guardrail sends messages to a validation LLM with a specialized system prompt that instructs it to detect:
- Stereotyping — Associating specific roles, characteristics, or behaviors with a particular gender (e.g., assuming women are more nurturing, men are more assertive)
- Unequal treatment — Indicating that one gender is superior/inferior or favoring one gender over another
- Discriminatory language — Using language that devalues, diminishes, or excludes a particular gender
- Gendered expectations — Imposing expectations based on gender (e.g., "As a man, you should be strong")
- Microaggressions — Subtle comments or assumptions that reinforce gender stereotypes
Configuration
"guardrails": [
  {
    "enabled": true,
    "before": true,
    "after": true,
    "id": "gender_bias",
    "config": {
      "provider": "provider_xxxxxxxxx"
    }
  }
]
Field explanations
- enabled:
true— The guardrail is active - before:
true— The guardrail applies to user input before sending to the LLM - after:
true— The guardrail applies to the LLM response
Config section
| Parameter | Type | Required | Default | Description |
|---|---|---|---|---|
provider | string | Yes | — | Reference ID of the LLM provider used to evaluate messages for gender bias. Must be different from the main provider, unless a model is set. |
model | string | No | default model of the provider | Model of the validation provider used to judge the messages, for instance a smaller and faster one. With a model set, the guarded provider can judge its own messages with another of its models. |
err_msg | string | No | "This message has been blocked by the 'gender-bias' guardrail !" | Custom error message returned when a message is blocked. |
Guardrail example
If a user asks, "Why are women bad at driving?", the LLM will either block the request or reframe it in a neutral way before processing it.
If a response contains gender bias, it will be adjusted before being displayed.