Learning mode
Monitoring mode answers what would this have done. It does not answer so can I turn it on — and that second question is why teams sit in monitoring for eight months. Nobody ever converts the events into a decision, because doing so by hand means reading a log pipeline, grouping it, judging each rule, and guessing at the residue.
A learning run does that conversion. It counts what matched over a window, proposes the exclusions that account for it — each one run through the tuning assistant's own preview — and says plainly what arming today would still break.
Find it under Threat Protection → WAF learning mode.
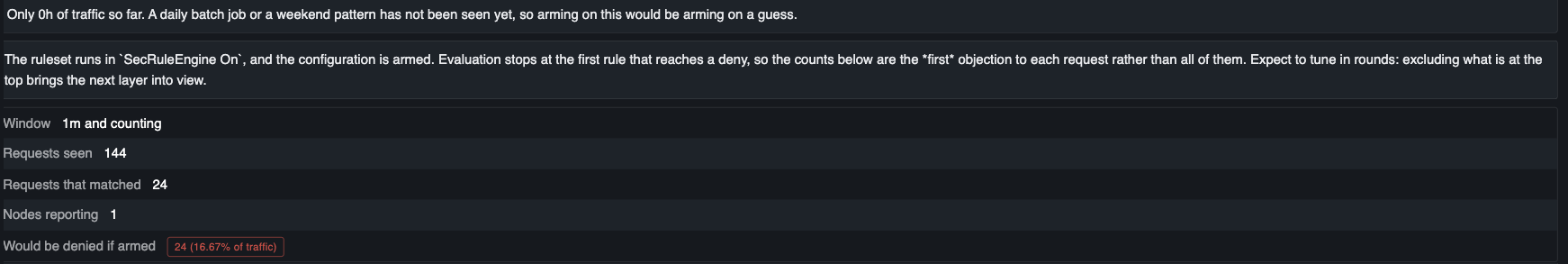
The verdict comes first and is usually an honest "not yet". Below it, what the window actually
measured — and Requests that matched counts requests where a rule objected to an input, not every
request the engine emitted an event for.
What it measures
| Requests seen | Every request the configuration evaluated. The denominator of every rate below |
| Requests that matched | Requests where a rule objected to something the caller sent. Not requests the engine emitted an event for — the CRS fires its initialisation rules on all of them |
| Would be denied if armed | Requests the ruleset reached a deny on while nothing was being denied. This is the number the decision turns on |
| Nodes reporting | Each node counts locally and flushes a snapshot; the report adds them up |
A run survives restarts and covers the whole cluster. Counting happens in memory on the request path and is flushed on a timer, so a window costs nothing measurable per request. A node that restarts — or joins — mid-window picks it back up from the shared state rather than sitting the rest of it out.
On a leader/worker Otoroshi, the workers serve the traffic and the leader serves this page. Without a dedicated redis the workers' counts never reach it, and the report is measuring one node that saw no traffic. It refuses to be read as anything else, but the fix is a redis.
Which engine mode to run it in
This matters more than it looks, and neither answer is simply better.
SecRuleEngine On, with the configuration in monitoring (block: false) is the normal rollout
and the one the arming estimate is accurate on, because it is literally what production will do.
The engine stops at the first rule that reaches a deny, so the inventory is the first objection to
each request rather than all of them. Expect to tune in rounds: excluding what is at the top brings
the next layer into view.
SecRuleEngine DetectionOnly evaluates every rule, so the inventory is complete in one pass.
But the engine keeps only the last phase's verdict in this mode, so an earlier deny is lost and the
arming estimate cannot be trusted — the report withholds it rather than printing zero, which
would be the most dangerous number on the page.
The report says which mode it is reading and what that mode can and cannot tell you. If you are deciding whether to arm, run the first.
What it proposes
For each noisy group above a floor of three matches, the report generates the narrowest exclusion that would silence it and runs it — the same measurement the tuning assistant makes:
- verified and clean → offered with a checkbox, ready to apply
- gives up known attacks in the same input → shown, marked needs a decision, not selectable in bulk
- ineffective or unverifiable → shown with the reason
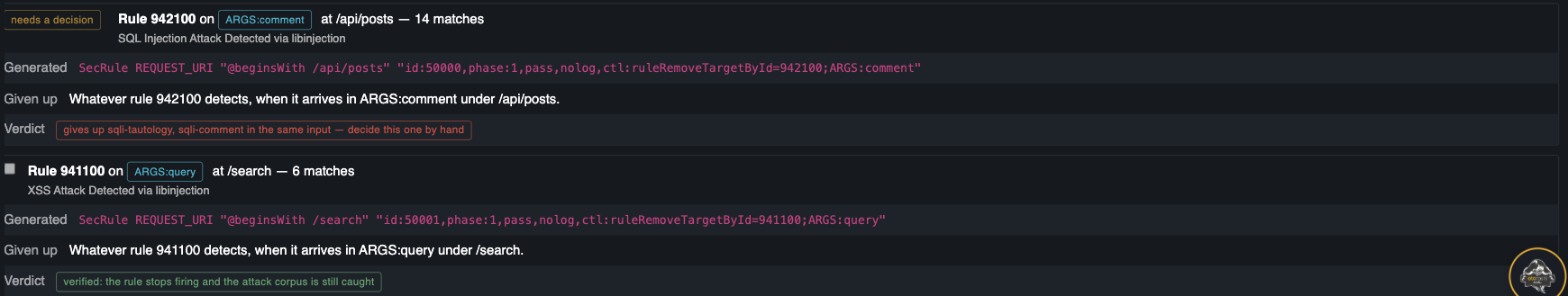
The same measurement the tuning assistant makes, applied to a whole window. Only the green one can be applied in bulk.
It also reports two configuration-level options, which sometimes replace a page of exclusions:
Paranoia level. If a clear majority of what matched comes from rules above the level you are running, the level was raised past what this traffic tolerates and one line beats forty exclusions. The report only recommends a drop when the evidence is one-sided, and always states what the drop gives up.
Anomaly threshold. A curve rather than a number: at each candidate threshold, how many of the sampled denials would still have been denied. Raising it is blunter than an exclusion — it weakens every rule at once — so it is presented as a stopgap while exclusions are reviewed, not instead of them.
The residue
The most useful line on the page is the last one:
Of 8 sampled requests the ruleset would have denied, 3 are fully accounted for by the exclusions above and 5 are not.

Counting how often each rule fires says nothing about how many requests stop breaking, because a denial under anomaly scoring is usually several rules agreeing. So the run keeps a bounded reservoir of the actual combinations, and a sample counts as resolved only when every rule that fired on it is excluded. That understates the improvement — a partial exclusion can still drop a request under the threshold — which is the direction an estimate offered before arming should err in.
The verdict
One sentence, first on the page, and usually an honest not yet:
| Situation | What it says |
|---|---|
| Under a day of traffic | A daily batch or a weekend pattern has not been seen, so arming would be arming on a guess |
| The mode cannot measure arming | The inventory is the tuning backlog, not a green light |
| Nothing would have been denied | This configuration looks safe to arm |
| Everything is accounted for | The verified exclusions cover every sampled denial |
| Some residue remains | How much, and how many candidates need a human |
Applying
Nothing is applied on its own. Selecting exclusions and applying writes them through exactly the path a hand-written one goes through: each is re-run and refused if it does not measurably stop the rule firing, and each lands in the configuration's own exclusions ruleset with the reason, the author and the match count recorded beside it. See where the assistant writes.
Applying also emits a CloudApimWafLearningAudit carrying the window the decision was taken on —
its duration, its request count, its impact estimate — so the evidence stays attached to the change.
A reasonable sequence
- Put the configuration in monitoring (
block: false), leave the ruleset inSecRuleEngine On. - Start a window and leave it for a full traffic cycle — a week catches the weekly job.
- Read the verdict. If it says the window is too short, it is.
- Apply the verified exclusions; decide the flagged ones by hand.
- Start a second window. The first round of exclusions will have brought the next layer into view.
- When the residue reaches zero and the window is long enough, arm it.
Tuning lists the same steps for someone doing it by hand. Learning mode is that checklist with the measurements taken for you.