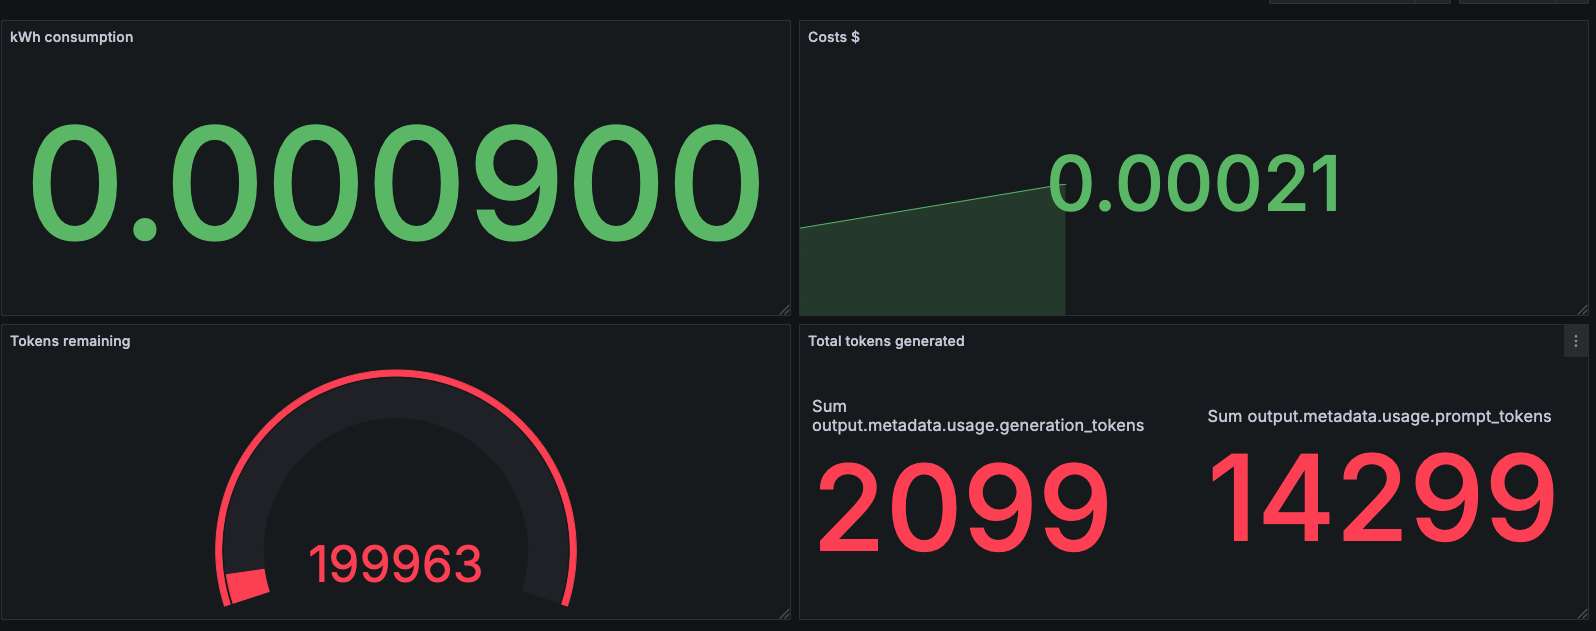
💰 Cost tracking
Cost tracking for LLMs with a gateway means monitoring and managing the costs of using different LLMs through an API gateway.
Our Otoroshi LLM extension helps you optimize usage, control your budget, and improve cost efficiency across models.
You can track the cost of each request and generate reports for each model.
If you want to track the costs of your LLM Usage, you can enable it in the Otoroshi LLM Extension (it should be enabled by default)
Configuration
costs-tracking {
  enabled = true
  enabled = ${?CLOUD_APIM_EXTENSIONS_LLM_EXTENSION_COSTS_TRACKING_ENABLED}
  embed-costs-tracking-in-responses = false
  embed-costs-tracking-in-responses = ${?CLOUD_APIM_EXTENSIONS_LLM_EXTENSION_COSTS_TRACKING_EMBED_COSTS_TRACKING_IN_RESPONSES}
  custom-prices = "{}"
  custom-prices = ${?CLOUD_APIM_EXTENSIONS_LLM_EXTENSION_COSTS_TRACKING_CUSTOM_PRICES}
  openrouter-catalog {
    enabled = false
    enabled = ${?CLOUD_APIM_EXTENSIONS_LLM_EXTENSION_COSTS_TRACKING_OPENROUTER_CATALOG_ENABLED}
    refresh-every = 6 hours
    refresh-every = ${?CLOUD_APIM_EXTENSIONS_LLM_EXTENSION_COSTS_TRACKING_OPENROUTER_CATALOG_REFRESH_EVERY}
  }
  models-catalog {
    enabled = true
    enabled = ${?CLOUD_APIM_EXTENSIONS_LLM_EXTENSION_COSTS_TRACKING_MODELS_CATALOG_ENABLED}
    price-currencies {
      scaleway = eur
    }
  }
  exchange-rates {
    eur = 1.17
    eur = ${?CLOUD_APIM_EXTENSIONS_LLM_EXTENSION_COSTS_TRACKING_EXCHANGE_RATES_EUR}
  }
  price-currencies {
    scaleway = eur
    ovhcloud = eur
  }
}
| Parameter | Type | Default | Description |
|---|---|---|---|
enabled | boolean | true | Enable or disable cost tracking |
embed-costs-tracking-in-responses | boolean | false | Always embed costs in LLM responses |
custom-prices | string (JSON) | "{}" | Custom model prices in LiteLLM format (see below) |
openrouter-catalog.enabled | boolean | false | Keep OpenRouter model prices in sync with its public catalog. Opt-in: it is the only outbound call the extension makes on its own |
openrouter-catalog.refresh-every | duration | 6 hours | How often the OpenRouter catalog is refreshed |
models-catalog.enabled | boolean | true | Price the models the price table does not know with the bundled models.dev catalog |
models-catalog.price-currencies | object | { scaleway = eur } | The currency of the models.dev prices of a provider, when not dollars |
exchange-rates | object | { eur = 1.17 } | How many dollars one unit of a currency is worth, to convert the prices published in that currency |
price-currencies | object | { scaleway = eur, ovhcloud = eur } | The currency of the price table prices of a provider (your custom-prices included), when not dollars |
Once it's enabled, audit events of kind LLMUsageAudit will have a costs object.
You can also embed the costs value in your LLM responses using the costs-tracking.embed-costs-tracking-in-responses config or by adding ?embed_costs=true to your query.
Price computation
Costs are always billed from the most accurate source available for the call:
- The price reported by the provider: when a provider bills the call back to us, that exact amount is used, whatever the model. OpenRouter does, which means every one of its models is priced correctly, including the ones no price table knows about, and including its per-provider routing and BYOK pricing. Costs sourced this way are marked
"source": "provider". - The model price table, used whenever the provider reports nothing, resolved in this order:
- User-defined prices: your own prices via the
custom-pricesconfig, which always win - Built-in custom prices: additional prices shipped by the extension for models absent from LiteLLM
- Built-in LiteLLM prices: the full LiteLLM model price dictionary, bundled with the extension
- The OpenRouter catalog, when enabled, kept in sync with the prices OpenRouter publishes, so new models are priced the day they ship
- The models.dev catalog, bundled with the extension, which prices thousands of models across more than 200 providers. It is only used for the provider that actually serves the model, and it recognizes the many ways providers spell a model id:
models/gemini-2.5-flash, dated snapshots likeclaude-sonnet-4-5-20250929,claude-sonnet-4.5versusclaude-sonnet-4-5, and so on. Prices sourced this way are the ones a model shows in its enriched/modelsentry, with"source": "models.dev"
- User-defined prices: your own prices via the
OpenRouter model variants and aliases — anthropic/claude-opus-5:batch, ~vendor/model-latest — are billed at the price of the model they point to.
Supported modalities
Costs are computed for the modalities the price grid bills per token:
| Modality | Cost tracking |
|---|---|
| Text (chat, completion, responses) | ✅ |
| Embeddings | ✅ |
| Moderation | ✅ (free on most providers, so the cost is a legitimate zero) |
| Image, audio, video, OCR | ❌ not yet — these are billed per image, pixel, second, character or page |
Calls on the modalities without cost tracking still count their tokens and pages against your budgets; only the dollar amount is missing.
Supported providers
Cost tracking natively supports the following providers, and every other provider the models.dev catalog knows (Together AI, Fireworks AI, DeepInfra, Nebius, Novita, Nvidia NIM, Perplexity, Cerebras, Z.AI...):
- openai
- deepseek
- x-ai
- azure-openai
- cloudflare
- gemini
- mistral 🇫🇷 🇪🇺
- ollama
- cohere
- anthropic
- groq
- openrouter (billed on the exact amount OpenRouter reports for each call)
- scaleway 🇫🇷 🇪🇺 and ovh-ai-endpoints 🇫🇷 🇪🇺 (priced in euros, see below)
- huggingface (billed at the models.dev price of the model, whatever inference provider the router picks for it,
:togetheror:fastestincluded)
Prices in euros
Costs and budgets are in dollars. Scaleway and OVHcloud publish their prices in euros, so their prices are converted
with the exchange-rates.eur rate before a call is billed or a price is shown: set it to the rate your finance team
works with. The enriched models of these providers tell which
currency their prices come from and the rate applied, in sources.pricing.
price-currencies tells which providers publish their prices in another currency, models-catalog.price-currencies
does the same for the models.dev catalog. Add a currency and its rate to price any other provider the same way: a
price in a currency with no rate is never billed.
For unsupported providers, you can set metadata on the provider entity to map it to a supported provider/model:
costs-tracking-provider: the provider name used for price lookupcosts-tracking-model: the model name used for price lookup
Refusing what cannot be priced
Any provider — text, image, embedding, audio, video, moderation or OCR — can require that every model it
serves has a known price, with the Require known costs switch (models.require_known_costs on the entity).
When it is on:
- a call using a model with no known price is rejected before the provider is ever contacted, so nothing is spent and nothing escapes your budgets
/modelsstops advertising the models it would refuse, so callers only ever see what you can bill
Leave it off — the default — to keep serving models whose price you do not track.
{
  "models": {
    "include": [],
    "exclude": [],
    "require_known_costs": true
  }
}
Custom prices
You can define custom per-model prices using the custom-prices config parameter. The format follows the LiteLLM price dictionary structure:
{
  "my-provider/my-model": {
    "input_cost_per_token": 0.000001,
    "output_cost_per_token": 0.000002,
    "output_cost_per_reasoning_token": 0.000005
  }
}
Available pricing fields:
| Field | Description |
|---|---|
input_cost_per_token | Cost per input token |
output_cost_per_token | Cost per output token |
output_cost_per_reasoning_token | Cost per reasoning token (falls back to output_cost_per_token if not set) |
input_cost_per_image | Cost per input image |
output_cost_per_image | Cost per output image |
Cost output
Each response with cost tracking includes:
{
  "input_cost": 0.00000165,
  "output_cost": 0.0000108,
  "reasoning_cost": 0,
  "total_cost": 0.00001245,
  "currency": "dollar",
  "source": "price-table"
}
source tells you where the amount comes from: provider when the provider billed the call back to us, price-table when it was computed from token counts and a model price.
Example of costs tracking embed in responses
NOTE: you can embed costs tracking informations by using embed_costs=true query param
$ curl --request POST \
  --url 'http://test.oto.tools:9999/v1/chat/completions?embed_costs=true' \
  --header 'authorization: Bearer otoapk_mqXJ9YrgVM0rcGZy_0a35ab6e5b5407cc7200f94f43f60c583928d372ef43b99a28b93243c3c90153' \
  --header 'content-type: application/json' \
  --data '{
  "messages": [
    {
      "role": "user",
      "content": "tell me a joke"
    }
  ]
}'
Response from the LLM :
{
  "id": "chatcmpl-VRyJP4WKPFG2bWODCKp0yXn3UkwtpdnQ",
  "object": "chat.completion",
  "created": 1743169375,
  "model": "gpt-4o-mini",
  "system_fingerprint": "fp-CGPX1MTbpRo7OvGCR0MPPwZiXz9sm8N0",
  "choices": [
    {
      "index": 0,
      "message": {
        "role": "assistant",
        "content": "Why did the scarecrow win an award?\n\nBecause he was outstanding in his field!"
      },
      "logprobs": null,
      "finish_reason": "stop"
    }
  ],
  "usage": {
    "prompt_tokens": 11,
    "completion_tokens": 18,
    "total_tokens": 29,
    "completion_tokens_details": {
      "reasoning_tokens": 0
    }
  },
  "costs": {
    "input_cost": 0.00000165,
    "output_cost": 0.0000108,
    "reasoning_cost": 0,
    "total_cost": 0.00001245,
    "currency": "dollar"
  }
}
Example of LLMUsageAudit event with cost tracking
{
  "@id" : "1905616593920983819",
  "@timestamp" : 1743169375292,
  "@type" : "AuditEvent",
  "@product" : "otoroshi",
  "@serviceId" : "",
  "@service" : "Otoroshi",
  "@env" : "dev",
  "audit" : "LLMUsageAudit",
  "provider_kind" : "openai",
  "provider" : "provider_10bbc76d-7cd8-4cb7-b760-61e749a1b691",
  "duration" : 415,
  "model" : "gpt-4o-mini",
  "rate_limit" : {
    "requests_limit" : 10000,
    "requests_remaining" : 9999,
    "tokens_limit" : 200000,
    "tokens_remaining" : 199993
  },
  "usage" : {
    "prompt_tokens" : 11,
    "generation_tokens" : 18,
    "reasoning_tokens" : 0
  },
  "error" : null,
  "consumed_using" : "chat/completion/blocking",
  "user" : null,
  "apikey" : null,
  "route" : {
    "_loc" : {
      "tenant" : "default",
      "teams" : [ "default" ]
    },
    "id" : "route_e4a9d6cb3-d859-4203-a860-8d1dd6d09557",
    "name" : "test",
    "description" : "A new route",
    "tags" : [ ],
    "metadata" : {
      "created_at" : "2025-03-28T10:10:19.448+01:00",
      "updated_at" : "2025-03-28T10:48:48.218+01:00"
    },
    "enabled" : true,
    "debug_flow" : false,
    "export_reporting" : false,
    "capture" : false,
    "groups" : [ "default" ],
    "bound_listeners" : [ ],
    "frontend" : {
      "domains" : [ "test.oto.tools" ],
      "strip_path" : true,
      "exact" : false,
      "headers" : { },
      "query" : { },
      "methods" : [ ]
    },
    "backend" : {
      "targets" : [ {
        "id" : "target_1",
        "hostname" : "request.otoroshi.io",
        "port" : 443,
        "tls" : true,
        "weight" : 1,
        "backup" : false,
        "predicate" : {
          "type" : "AlwaysMatch"
        },
        "protocol" : "HTTP/1.1",
        "ip_address" : null,
        "tls_config" : {
          "certs" : [ ],
          "trusted_certs" : [ ],
          "enabled" : false,
          "loose" : false,
          "trust_all" : false
        }
      } ],
      "root" : "/",
      "rewrite" : false,
      "load_balancing" : {
        "type" : "RoundRobin"
      },
      "client" : {
        "retries" : 1,
        "max_errors" : 20,
        "retry_initial_delay" : 50,
        "backoff_factor" : 2,
        "call_timeout" : 30000,
        "call_and_stream_timeout" : 120000,
        "connection_timeout" : 10000,
        "idle_timeout" : 60000,
        "global_timeout" : 30000,
        "sample_interval" : 2000,
        "proxy" : { },
        "custom_timeouts" : [ ],
        "cache_connection_settings" : {
          "enabled" : false,
          "queue_size" : 2048
        }
      },
      "health_check" : {
        "enabled" : false,
        "url" : "",
        "timeout" : 5000,
        "healthyStatuses" : [ ],
        "unhealthyStatuses" : [ ]
      }
    },
    "backend_ref" : null,
    "plugins" : [ {
      "enabled" : true,
      "debug" : false,
      "plugin" : "cp:otoroshi.next.plugins.OverrideHost",
      "include" : [ ],
      "exclude" : [ ],
      "config" : { },
      "bound_listeners" : [ ],
      "plugin_index" : {
        "transform_request" : 0
      }
    }, {
      "enabled" : true,
      "debug" : false,
      "plugin" : "cp:otoroshi_plugins.com.cloud.apim.otoroshi.extensions.aigateway.plugins.OpenAiCompatProxy",
      "include" : [ ],
      "exclude" : [ ],
      "config" : {
        "refs" : [ "provider_10bbc76d-7cd8-4cb7-b760-61e749a1b691" ]
      },
      "bound_listeners" : [ ],
      "plugin_index" : { }
    } ]
  },
  "input_prompt" : [ {
    "role" : "user",
    "content" : "tell me a joke"
  } ],
  "output" : {
    "generations" : [ {
      "message" : {
        "role" : "assistant",
        "content" : "Why did the scarecrow win an award?\n\nBecause he was outstanding in his field!"
      }
    } ],
    "metadata" : {
      "rate_limit" : {
        "requests_limit" : 10000,
        "requests_remaining" : 9999,
        "tokens_limit" : 200000,
        "tokens_remaining" : 199993
      },
      "usage" : {
        "prompt_tokens" : 11,
        "generation_tokens" : 18,
        "reasoning_tokens" : 0
      },
      "costs" : {
        "input_cost" : 0.00000165,
        "output_cost" : 0.0000108,
        "reasoning_cost" : 0,
        "total_cost" : 0.00001245,
        "currency" : "dollar"
      }
    }
  },
  "provider_details" : {
    "_loc" : {
      "tenant" : "default",
      "teams" : [ "default" ]
    },
    "id" : "provider_10bbc76d-7cd8-4cb7-b760-61e749a1b691",
    "name" : "OpenAI clean",
    "description" : "An OpenAI LLM api provider",
    "metadata" : {
      "created_at" : "2025-03-28T10:10:51.558+01:00"
    },
    "tags" : [ ],
    "provider" : "openai",
    "connection" : {
      "base_url" : "https://api.openai.com/v1",
      "token" : "xxx",
      "timeout" : 30000
    },
    "options" : {
      "model" : "gpt-4o-mini",
      "frequency_penalty" : null,
      "logit_bias" : null,
      "logprobs" : null,
      "top_logprobs" : null,
      "max_tokens" : null,
      "n" : 1,
      "presence_penalty" : null,
      "response_format" : null,
      "seed" : null,
      "stop" : null,
      "stream" : false,
      "temperature" : 1,
      "top_p" : 1,
      "tools" : null,
      "tool_choice" : null,
      "user" : null,
      "wasm_tools" : [ ],
      "mcp_connectors" : [ ],
      "allow_config_override" : true
    },
    "provider_fallback" : null,
    "context" : {
      "default" : null,
      "contexts" : [ ]
    },
    "models" : {
      "include" : [ ],
      "exclude" : [ ]
    },
    "guardrails" : [ ],
    "guardrails_fail_on_deny" : false,
    "cache" : {
      "strategy" : "none",
      "ttl" : 300000,
      "score" : 0.8
    }
  },
  "costs": {
    "input_cost": 0.00000165,
    "output_cost": 0.0000108,
    "reasoning_cost": 0,
    "total_cost": 0.00001245,
    "currency": "dollar"
  }
}
Dashboard example